Loading and saving graphical models
 |  |  |
pyAgrum can read and write graphical models in many file formats. This notebook gives an overview of which formats are available for each model type, what they preserve, and why the native bgum (binary) and jgum (JSON) formats are the best choice for pyAgrum workflows.
import osimport tempfileimport time
import pyagrum as gumimport pyagrum.lib.notebook as gnb
Available formats
Section titled “Available formats”The three main model types each have their own set of supported formats.
print(f"BayesNet formats : {gum.availableBNExts()}")print(f"InfluenceDiagram : {gum.availableIDExts()}")print(f"MarkovRandomField : {gum.availableMRFExts()}")BayesNet formats : bif|dsl|net|bifxml|o3prm|uai|xdsl|pkl|jgum|bgumInfluenceDiagram : xmlbif|bifxml|xml|jgum|bgum|pklMarkovRandomField : uai|jgum|bgum|pklThe load/save API is uniform across model types:
| Model | Load | Save |
|---|---|---|
BayesNet | gum.loadBN(filename) | gum.saveBN(bn, filename) |
InfluenceDiagram | gum.loadID(filename) | gum.saveID(diag, filename) |
MarkovRandomField | gum.loadMRF(filename) | gum.saveMRF(mrf, filename) |
The format is selected automatically from the file extension.
Bayesian networks
Section titled “Bayesian networks”A tour of BN formats
Section titled “A tour of BN formats”Let’s load the classic Asia network and save/reload it in every available format, comparing file size and round-trip speed.
bn_asia = gum.loadBN("res/asia.bgum")gnb.flow.row(bn_asia, captions=[f"Asia BN — {bn_asia.size()} nodes, {bn_asia.sizeArcs()} arcs"])def benchmark_bn(bn, exts): """Save and reload a BN in every given format, return a comparison table.""" rows = [] with tempfile.TemporaryDirectory() as d: for ext in exts.split("|"): fname = os.path.join(d, f"model.{ext}") try: t0 = time.perf_counter() gum.saveBN(bn, fname) t_save = time.perf_counter() - t0 size = os.path.getsize(fname) t0 = time.perf_counter() bn2 = gum.loadBN(fname) t_load = time.perf_counter() - t0 names_ok = sorted(bn.names()) == sorted(bn2.names()) labels_ok = names_ok and all( list(bn.variable(n).labels()) == list(bn2.variable(n).labels()) for n in bn.names() ) types_ok = names_ok and all(bn.variable(n).varType() == bn2.variable(n).varType() for n in bn.names()) rows.append((ext, size, t_save * 1000, t_load * 1000, names_ok, labels_ok, types_ok)) except Exception as e: rows.append((ext, None, None, None, False, False, str(e)[:60])) return rows
rows = benchmark_bn(bn_asia, gum.availableBNExts())
header = ( f"{'ext':8s} {'size (B)':>9s} {'save (ms)':>10s} {'load (ms)':>10s} {'names':>5s} {'labels':>6s} {'types':>5s}")print(header)print("-" * len(header))for ext, size, ts, tl, n_ok, l_ok, t_ok in rows: if size is not None: print(f"{ext:8s} {size:9d} {ts:10.3f} {tl:10.3f} {n_ok!s:>5s} {l_ok!s:>6s} {t_ok!s:>5s}") else: print(f"{ext:8s} (unsupported for this model)")ext size (B) save (ms) load (ms) names labels types-----------------------------------------------------------------bif 1554 0.278 0.186 True True Falsedsl 1872 0.129 0.113 True True Falsenet 2558 0.106 0.108 True True Falsebifxml 3554 0.108 0.111 True True Trueo3prm (unsupported for this model)uai 430 0.100 0.064 False False Falsexdsl 2264 0.354 0.079 True True Falsepkl 1339 0.136 0.098 True True Truejgum 1283 0.073 0.056 True True Truebgum 808 0.070 0.050 True True Trueimport matplotlib.pyplot as pltimport numpy as np
exts = [r[0] for r in rows if r[1] is not None]sizes = [r[1] for r in rows if r[1] is not None]t_saves = [r[2] for r in rows if r[1] is not None]t_loads = [r[3] for r in rows if r[1] is not None]
x = np.arange(len(exts))width = 0.35
fig, (ax1, ax2) = plt.subplots(1, 2, figsize=(12, 4))
ax1.bar(x, sizes, color="steelblue")ax1.set_xticks(x)ax1.set_xticklabels(exts, rotation=45)ax1.set_ylabel("size (B)")ax1.set_title("File size per format")
ax2.bar(x - width / 2, t_saves, width, label="save (ms)", color="darkorange")ax2.bar(x + width / 2, t_loads, width, label="load (ms)", color="seagreen")ax2.set_xticks(x)ax2.set_xticklabels(exts, rotation=45)ax2.set_ylabel("time (ms)")ax2.set_title("Save / load time per format")ax2.legend()
fig.tight_layout()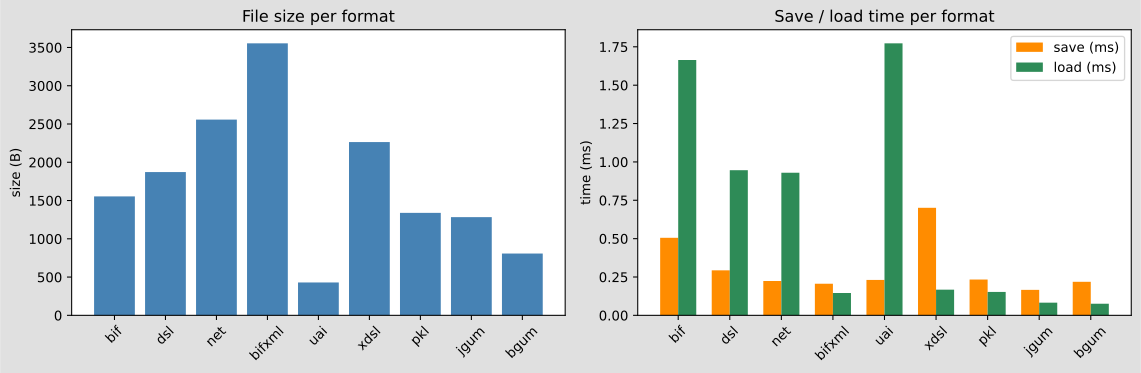
Variable type fidelity
Section titled “Variable type fidelity”Many real-world networks contain variables of heterogeneous types: labelled (LabelizedVariable), integer ranges (RangeVariable) or discretized continuous domains (DiscretizedVariable). Not all formats can represent these faithfully.
## Build a BN that mixes all main variable typesbn_mixed = gum.BayesNet("mixed_types")bn_mixed.add(gum.LabelizedVariable("Smoker", "Smoker", ["yes", "no"]))bn_mixed.add(gum.RangeVariable("Age", "Age", 20, 60))bn_mixed.add(gum.DiscretizedVariable("Temp", "Temp", [36.0, 37.0, 38.5, 42.0]))bn_mixed.add(gum.LabelizedVariable("Cancer", "Cancer", ["yes", "no"]))bn_mixed.addArc("Smoker", "Cancer")bn_mixed.addArc("Age", "Cancer")bn_mixed.addArc("Temp", "Cancer")bn_mixed.cpt("Smoker").fillWith([0.3, 0.7])bn_mixed.cpt("Age").fillWith(1).normalize()bn_mixed.cpt("Temp").fillWith(1).normalize()bn_mixed.cpt("Cancer").fillWith(1).normalize()
print("Variable types in bn_mixed:")type_names = {  gum.VarType_LABELIZED: "Labelized",  gum.VarType_DISCRETIZED: "Discretized",  gum.VarType_RANGE: "Range",  gum.VarType_INTEGER: "Integer",  gum.VarType_NUMERICAL: "Numerical",}for n in bn_mixed.names():  v = bn_mixed.variable(n)  print(f"  {n:10s}: {type_names.get(v.varType(), f'type={v.varType()}')}")
Variable types in bn_mixed: Smoker : Labelized Temp : Discretized Cancer : Labelized Age : Rangerows = benchmark_bn(bn_mixed, gum.availableBNExts())
header = ( f"{'ext':8s} {'size (B)':>9s} {'save (ms)':>10s} {'load (ms)':>10s} {'names':>5s} {'labels':>6s} {'types':>5s}")print(header)print("-" * len(header))for ext, size, ts, tl, n_ok, l_ok, t_ok in rows: if size is not None: print(f"{ext:8s} {size:9d} {ts:10.3f} {tl:10.3f} {n_ok!s:>5s} {l_ok!s:>6s} {t_ok!s:>5s}") else: print(f"{ext:8s} (unsupported for this model)")ext size (B) save (ms) load (ms) names labels types-----------------------------------------------------------------bif (unsupported for this model)dsl (unsupported for this model)net (unsupported for this model)bifxml 8951 0.301 0.208 True True Trueo3prm (unsupported for this model)uai 6703 0.220 0.263 False False Falsexdsl 7882 0.737 0.185 True True Falsepkl 12187 0.319 0.178 True True Truejgum 12131 0.203 0.133 True True Truebgum 5158 0.167 0.100 True True TrueObservations for BN:
| Format | Notes |
|---|---|
bif, dsl, net | Classic, widely used, but do not support DiscretizedVariable |
bifxml / xdsl | XML-based; bifxml preserves types, xdsl does not |
uai | Compact but loses variable names |
o3prm | Verbose; requires a full class hierarchy |
pkl | Python pickle; preserves everything but not portable across pyAgrum versions |
jgum | Native JSON format; preserves all types, human-readable |
bgum | Native binary format; smallest files, fastest I/O, preserves all types |
Influence diagrams
Section titled “Influence diagrams”Influence diagrams have fewer supported formats than BNs.
## Classic Oil Wildcatter influence diagramdiag = gum.loadID("res/OilWildcatter.bgum")gnb.flow.row(diag, captions=[f"Oil Wildcatter — {diag.size()} nodes"])def benchmark_id(diag, exts): rows = [] with tempfile.TemporaryDirectory() as d: for ext in exts.split("|"): fname = os.path.join(d, f"model.{ext}") try: t0 = time.perf_counter() gum.saveID(diag, fname) t_save = time.perf_counter() - t0 size = os.path.getsize(fname) t0 = time.perf_counter() diag2 = gum.loadID(fname) t_load = time.perf_counter() - t0 names_ok = sorted(diag.names()) == sorted(diag2.names()) rows.append((ext, size, t_save * 1000, t_load * 1000, names_ok)) except Exception as e: rows.append((ext, None, None, None, str(e)[:60])) return rows
rows = benchmark_id(diag, gum.availableIDExts())
header = f"{'ext':8s} {'size (B)':>9s} {'save (ms)':>10s} {'load (ms)':>10s} {'names':>5s}"print(header)print("-" * len(header))for ext, size, ts, tl, n_ok in rows: if size is not None: print(f"{ext:8s} {size:9d} {ts:10.3f} {tl:10.3f} {n_ok!s:>5s}") else: print(f"{ext:8s} (unsupported for this model)")ext size (B) save (ms) load (ms) names--------------------------------------------------xmlbif 2730 0.324 0.203 Truebifxml 2730 0.141 0.097 Truexml 2730 0.100 0.073 Truejgum 751 0.107 0.073 Truebgum 711 0.089 0.049 Truepkl 828 0.108 0.073 TrueObservations for InfluenceDiagram:
| Format | Notes |
|---|---|
bifxml / xmlbif / xml | Three aliases for the same XML format |
pkl | Portable only within the same pyAgrum version |
jgum | Compact JSON, fully faithful, human-readable |
bgum | Smallest files, fastest I/O |
Markov random fields
Section titled “Markov random fields”MRFs have the smallest set of supported formats.
mrf = gum.fastMRF("A{yes|no}--B{low|mid|high}--C{yes|no}--A;B--D{yes|no}")gnb.flow.row(mrf, captions=[f"MRF — {mrf.size()} nodes, {mrf.sizeEdges()} edges"])def benchmark_mrf(mrf, exts): rows = [] with tempfile.TemporaryDirectory() as d: for ext in exts.split("|"): fname = os.path.join(d, f"model.{ext}") try: t0 = time.perf_counter() gum.saveMRF(mrf, fname) t_save = time.perf_counter() - t0 size = os.path.getsize(fname) t0 = time.perf_counter() mrf2 = gum.loadMRF(fname) t_load = time.perf_counter() - t0 names_ok = sorted(mrf.names()) == sorted(mrf2.names()) labels_ok = names_ok and all( list(mrf.variable(n).labels()) == list(mrf2.variable(n).labels()) for n in mrf.names() ) rows.append((ext, size, t_save * 1000, t_load * 1000, names_ok, labels_ok)) except Exception as e: rows.append((ext, None, None, None, False, str(e)[:60])) return rows
rows = benchmark_mrf(mrf, gum.availableMRFExts())
header = f"{'ext':8s} {'size (B)':>9s} {'save (ms)':>10s} {'load (ms)':>10s} {'names':>5s} {'labels':>6s}"print(header)print("-" * len(header))for ext, size, ts, tl, n_ok, l_ok in rows: if size is not None: print(f"{ext:8s} {size:9d} {ts:10.3f} {tl:10.3f} {n_ok!s:>5s} {l_ok!s:>6s}") else: print(f"{ext:8s} (unsupported for this model)")ext size (B) save (ms) load (ms) names labels----------------------------------------------------------uai 285 0.195 0.123 False Falsejgum 675 0.125 0.101 True Truebgum 426 0.071 0.055 True Truepkl 756 0.502 0.205 True TrueObservations for MRF:
| Format | Notes |
|---|---|
uai | Only standard MRF format, but loses variable names and labels |
pkl | Portable only within the same pyAgrum version |
jgum | Full fidelity, JSON, readable |
bgum | Smallest, fastest, full fidelity |
Why bgum and jgum are the best choice for pyAgrum
Section titled “Why bgum and jgum are the best choice for pyAgrum”The bgum and jgum formats are the native aGrUM formats, designed specifically for all model types supported by pyAgrum. They share the same advantages:
- Universal — same format works for
BayesNet,InfluenceDiagramandMarkovRandomField. - Full fidelity — all variable types (
LabelizedVariable,RangeVariable,DiscretizedVariable,IntegerVariable) are preserved exactly. - Fast — both I/O are among the fastest of all formats.
- Compact —
bgumtypically produces the smallest files;jgumis still compact while remaining human-readable. - No external dependencies — no need for third-party parsers.
The only difference between the two is readability:
bgum(binary) — optimal for production workflows, automated pipelines, storing large models.jgum(JSON) — easier to inspect, diff, or version-control.
Quick demo: round-trip with bgum and jgum
Section titled “Quick demo: round-trip with bgum and jgum”## Build a BN with mixed variable types to stress-test fidelitybn_demo = gum.BayesNet("demo")bn_demo.add(gum.LabelizedVariable("Smoker", "Smoker", ["yes", "no"]))bn_demo.add(gum.RangeVariable("Age", "Age", 20, 60))bn_demo.add(gum.DiscretizedVariable("Temp", "Temp", [36.0, 37.0, 38.5, 42.0]))bn_demo.add(gum.LabelizedVariable("Cancer", "Cancer", ["yes", "no"]))bn_demo.addArc("Smoker", "Cancer")bn_demo.addArc("Age", "Cancer")bn_demo.addArc("Temp", "Cancer")bn_demo.cpt("Smoker").fillWith([0.3, 0.7])bn_demo.cpt("Age").fillWith(1).normalize()bn_demo.cpt("Temp").fillWith(1).normalize()bn_demo.cpt("Cancer").fillWith(1).normalize()
type_names = { gum.VarType_LABELIZED: "Labelized", gum.VarType_DISCRETIZED: "Discretized", gum.VarType_RANGE: "Range", gum.VarType_INTEGER: "Integer", gum.VarType_NUMERICAL: "Numerical",}
print("Variable types before save:")for n in bn_demo.names(): v = bn_demo.variable(n) print( f" {n:8s}: {type_names.get(v.varType(), f'type={v.varType()}'):12s} labels={list(v.labels()[:4])}{'...' if v.domainSize() > 4 else ''}" )Variable types before save: Smoker : Labelized labels=['yes', 'no'] Temp : Discretized labels=['[36;37[', '[37;38.5[', '[38.5;42]'] Cancer : Labelized labels=['yes', 'no'] Age : Range labels=['20', '21', '22', '23']...with tempfile.TemporaryDirectory() as d: for ext in ("bgum", "jgum"): fname = os.path.join(d, f"demo.{ext}") gum.saveBN(bn_demo, fname) bn2 = gum.loadBN(fname) print(f"\n--- {ext} ({os.path.getsize(fname)} bytes) ---") for n in bn2.names(): v = bn2.variable(n) print( f" {n:8s}: {type_names.get(v.varType(), f'type={v.varType()}'):12s} labels={list(v.labels()[:4])}{'...' if v.domainSize() > 4 else ''}" )--- bgum (5151 bytes) --- Smoker : Labelized labels=['yes', 'no'] Temp : Discretized labels=['[36;37[', '[37;38.5[', '[38.5;42]'] Cancer : Labelized labels=['yes', 'no'] Age : Range labels=['20', '21', '22', '23']...
--- jgum (12124 bytes) --- Smoker : Labelized labels=['yes', 'no'] Temp : Discretized labels=['[36;37[', '[37;38.5[', '[38.5;42]'] Cancer : Labelized labels=['yes', 'no'] Age : Range labels=['20', '21', '22', '23']...## jgum is plain JSON — easy to inspectimport json
with tempfile.TemporaryDirectory() as d: fname = os.path.join(d, "demo.jgum") gum.saveBN(bn_demo, fname) with open(fname) as f: data = json.load(f) # Show just the variable descriptions print(json.dumps(data.get("variables", data.get("nodes", {})), indent=2))[ "Smoker{yes|no}", "Age[20,60]", "Temp[36,37,38.5,42]", "Cancer{yes|no}"]bgum and jgum work identically for all model types
Section titled “bgum and jgum work identically for all model types”with tempfile.TemporaryDirectory() as d: # BayesNet gum.saveBN(bn_asia, os.path.join(d, "asia.bgum")) bn_rt = gum.loadBN(os.path.join(d, "asia.bgum")) print(f"BN round-trip via bgum: names match = {sorted(bn_asia.names()) == sorted(bn_rt.names())}")
# InfluenceDiagram gum.saveID(diag, os.path.join(d, "oil.bgum")) diag_rt = gum.loadID(os.path.join(d, "oil.bgum")) print(f"ID round-trip via bgum: names match = {sorted(diag.names()) == sorted(diag_rt.names())}")
# MarkovRandomField gum.saveMRF(mrf, os.path.join(d, "mrf.bgum")) mrf_rt = gum.loadMRF(os.path.join(d, "mrf.bgum")) print(f"MRF round-trip via bgum: names match = {sorted(mrf.names()) == sorted(mrf_rt.names())}")BN round-trip via bgum: names match = TrueID round-trip via bgum: names match = TrueMRF round-trip via bgum: names match = TrueI/O Summary
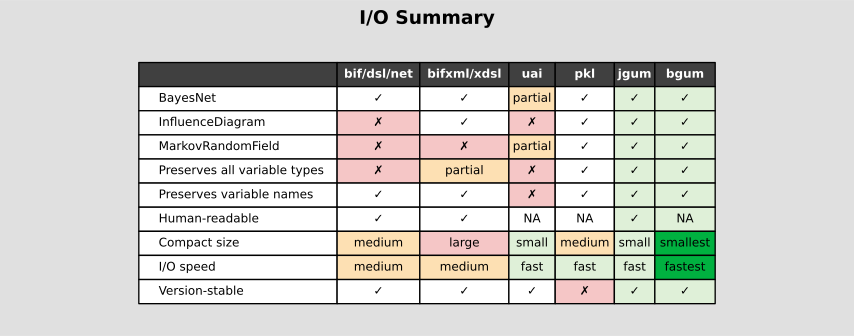
Section titled “I/O Summary”bif/dsl/net | bifxml/xdsl | uai | pkl | jgum | bgum | |
|---|---|---|---|---|---|---|
| BayesNet | ✓ | ✓ | partial | ✓ | ✓ | ✓ |
| InfluenceDiagram | ✗ | ✓ | ✗ | ✓ | ✓ | ✓ |
| MarkovRandomField | ✗ | ✗ | partial | ✓ | ✓ | ✓ |
| Preserves all variable types | ✗ | partial | ✗ | ✓ | ✓ | ✓ |
| Preserves variable names | ✓ | ✓ | ✗ | ✓ | ✓ | ✓ |
| Human-readable | ✓ | ✓ | ✓ | ✗ | ✓ | ✗ |
| Compact size | medium | large | small | medium | small | smallest |
| I/O speed | medium | medium | fast | fast | fast | fastest |
| Version-stable | ✓ | ✓ | ✓ | ✗ | ✓ | ✓ |
Recommendation:
- Use
bgumwhenever storage size or I/O speed matters, or when working with non-BN models. - Use
jgumwhen the file needs to be inspected, diffed, or stored in version control. - Use
bif/bifxmlonly when interoperability with other tools (GeNIe, Netica, …) is required.
import matplotlib.pyplot as plt
columns = ["", "bif/dsl/net", "bifxml/xdsl", "uai", "pkl", "jgum", "bgum"]rows = [  ["BayesNet", "✓", "✓", "partial", "✓", "✓", "✓"],  ["InfluenceDiagram", "✗", "✓", "✗", "✓", "✓", "✓"],  ["MarkovRandomField", "✗", "✗", "partial", "✓", "✓", "✓"],  ["Preserves all variable types", "✗", "partial", "✗", "✓", "✓", "✓"],  ["Preserves variable names", "✓", "✓", "✗", "✓", "✓", "✓"],  ["Human-readable", "✓", "✓", "NA", "NA", "✓", "NA"],  ["Compact size", "medium", "large", "small", "medium", "small", "smallest"],  ["I/O speed", "medium", "medium", "fast", "fast", "fast", "fastest"],  ["Version-stable", "✓", "✓", "✓", "✗", "✓", "✓"],]
RED = "#f5c6c6"  # same as crossesORANGE = "#fde0b3"  # same as partialLIGHTGREEN = "#dff0d8"  # same as check (jgum/bgum columns)FRANCEGREEN = "#00b140"  # smallest/fastest
SIZE_SPEED_COLORS = {  "large": RED,  "medium": ORANGE,  "small": LIGHTGREEN,  "fast": LIGHTGREEN,  "smallest": FRANCEGREEN,  "fastest": FRANCEGREEN,}
fig, ax = plt.subplots(figsize=(9, 3.6))ax.axis("off")ax.set_title("I/O Summary", fontsize=14, fontweight="bold", pad=12)
table = ax.table(cellText=rows, colLabels=columns, cellLoc="center", loc="center")table.auto_set_font_size(False)table.set_fontsize(9)table.scale(1, 1.4)table.auto_set_column_width(col=list(range(len(columns))))
green_cols = {5, 6}  # jgum, bgum: always green, whatever the value
for (row, col), cell in table.get_celld().items():  if row == 0:    cell.set_facecolor("#404040")    cell.set_text_props(color="white", fontweight="bold")    continue  if col == 0:    cell.set_text_props(ha="left")    continue
  label = rows[row - 1][0]  value = rows[row - 1][col]
  if label in ("Compact size", "I/O speed"):    cell.set_facecolor(SIZE_SPEED_COLORS[value])  elif col in green_cols:    cell.set_facecolor(LIGHTGREEN)  elif value == "✗":    cell.set_facecolor(RED)  elif value == "partial":    cell.set_facecolor(ORANGE)  elif value == "NA":    pass
fig.tight_layout()plt.show()